ZERO DATA RETENTION × HOONIFY — SWITCH CREDITS
Zero data retention is one line of code away.
Same API you already use. Frontier-quality open models at 10–50× less - and nothing kept after a request completes. You can't leak what isn't stored.
That's the whole migration. Up to $2,500 in switch credits for migrating one production route.

The Switch Kit
Everything you need to move a workload without a rewrite. PDF + eval script, straight to your inbox
Per-provider migration guide
Step-by-step instructions for moving off the OpenAI, Anthropic, and Gemini SDKs - what changes, what doesn't, and the gotchas.
The base_url swap
The two-line diff you saw above, ready to paste for every SDK and framework we support. That really is the whole migration.
Closed → open model mapping
Which open model to pick for the closed model you're leaving, matched on the work you actually run - not leaderboard vibes.
The eval script
Run your own prompts through both providers and diff the outputs before you commit. Trust your evals, not our marketing.
Or claim up to $2,500 in credits below
- Zero data retention by architecture - nothing stored, retained, or trained on after a request completes. Ever
- OpenAI-compatible - same SDK, same request shape, same workflow; the migration is one line
- 10–50× cheaper - a fraction of the closed-API invoice, no surge, no surprises
- Frontier quality - open models like GLM and Qwen match closed frontier on the work that ships
- No lock-in - swap back anytime; run in our cloud, your cloud, or fully air-gapped
Claim your switch credits
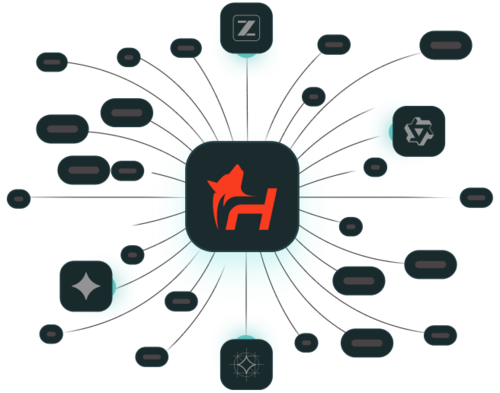
From closed API to first request in an afternoon
Submit the form
Your provider, rough volume, what the pipeline does. Under a minute, and the Switch Kit lands in your inbox.
Create an account
Sign up on Hoonify and acccept the $10 in credits first. No credit card, no sales call. You'll get a personalized one-time voucher code and an API key ready to use.
Swap one route, credits follow
Point base_url at Hoonify for a single production pipeline. Same SDK, same request shape, your code keeps working as-is. Up to $2,500 in switch credits lands in your account.
A policy is a setting. Architecture is a fact.
A retention policy
Is a setting someone else controls - and can quietly change. Your prompts sit in storage under rules that are one terms-of-service update away from being different rules.
Architectural zero retention
Means there is nothing to change. Requests are processed and discarded. There is no stored prompt corpus to train on, leak, or subpoena.
For teams where even that isn't enough: run Hoonify in your own cloud — or fully air-gapped.
Start with one route.
Nobody rips out a working stack over a ToS update - and you don't have to. Pick the one pipeline that handles data your provider shouldn't keep. Redirect it. Run our eval script side-by-side for a week. If the quality holds (it will - check for yourself), move the next one. Your Claude and GPT UI integrations stay the same.
This is our entire record of your request
The complete log line, verbatim. What billing and rate limiting need - and nothing else.
You can't leak, train on, or sell a field that doesn't exist.
What providers keep
Summarized from each provider's published documentation - every cell links its primary source. Spot something out of date? Tell us and we'll fix it.
| Provider | Retention window | Trains on your API data? | Zero retention |
|---|---|---|---|
| OpenAI | Abuse-monitoring logs (prompts, responses, metadata) kept up to 30 days — longer if required by law source ↗ | Not by default; explicit opt-in sharing exists source ↗ | By prior approval only; some endpoints excluded source ↗ |
| Anthropic | Content not retained by default — except designated “Covered Models,” which require 30-day retention source ↗ | Not without express permission source ↗ | On request via sales; batch, files, and Covered Models excluded source ↗ |
| Google Gemini | Opt-in logs expire after 55 days by default source ↗ | Paid tier: not used for product improvement by default; voluntarily shared datasets may be human-reviewed source ↗ | Available by request for qualifying projects source ↗ |
| Hoonify | Nothing stored after the request completes | Never | The default — no approval, no request, no tier |
What we're not claiming
An audience that diffs ToS documents for fun deserves the caveats up front.
“Open models win every benchmark”
They don't. They win on cost per task that ships. That's exactly what the eval script exists to measure - on your prompts, not a leaderboard's.
“Zero retention has no tradeoffs”
We can't replay your request to debug it, because we don't have it. That's the point. Bring your own tracing.
“Migration is always one line”
It is for OpenAI-SDK code paths. Provider-specific features need the mapping guide - budget an afternoon.
Switching pays for itself
You're not trading quality for privacy - open models match closed frontier on the work that ships. Run your own numbers:
GLM-5.2 / Qwen3.6 / Gemma-4 per-1M prices
The swap-back guarantee
Keep your old API key in your env. If your evals disagree with ours, moving back is the same one line - and you keep whatever credits you've already used. No exit meeting, no sales call, no “retention specialist.”
I rebuilt a dashboard that ties together my accounting, my CRM, everything — far more complex than what I’d built before with Codex, and it cost about $60 instead of $600 in tokens. If not less.
It ran so fast I thought it was broken.
Hoonify TurbOS was delivered as a private cloud solution, and improved their time-to-results by 20x.
We can reduce our initial analyst load by more than 90%. Our future is all the brighter thanks to Hoonify's involvement.
Is my data used for training?
Never. There is no stored prompt corpus to train on - requests are processed and discarded when they complete. That's architecture, not a policy toggle.
What do you log?
Operational metadata only: request timestamps, model ID, token counts, and status codes - what billing and rate limiting need to work. Never prompt or completion content.
Can you prove it?
Yes. Our architecture documentation and DPA spell out exactly what exists and for how long - ask and we'll send both. And for teams where even that isn't enough, Hoonify runs in your own cloud or fully air-gapped.
What about quality?
Open models like GLM and Qwen match closed frontier on the work that ships. Don't take our word for it - the Switch Kit includes an eval script to run your own prompts through both providers and diff the outputs. And because Hoonify is OpenAI-compatible, you can swap back anytime. No lock-in.
How do the switch credits work?
Move a production workload and get up to $2,500 in inference credits, applied to any model in the catalog. Submit the form, we verify the workload, and credits typically land within one business day.
What happens when the credits run out?
You move to standard transparent per-million-token pricing - typically 10–50× cheaper than closed APIs. No commitment, and you can leave anytime with your code.
See what your AI looks like when your data stays yours.
Up to $2,500 in switch credits for migrating a production workload - No credit card, no lock-in, live the same afternoon.
Claim your switch credits →